Researchers Reveal New Prompt‑Crafting Method That Lets Malicious Commands Slip Past AI Safety Filters
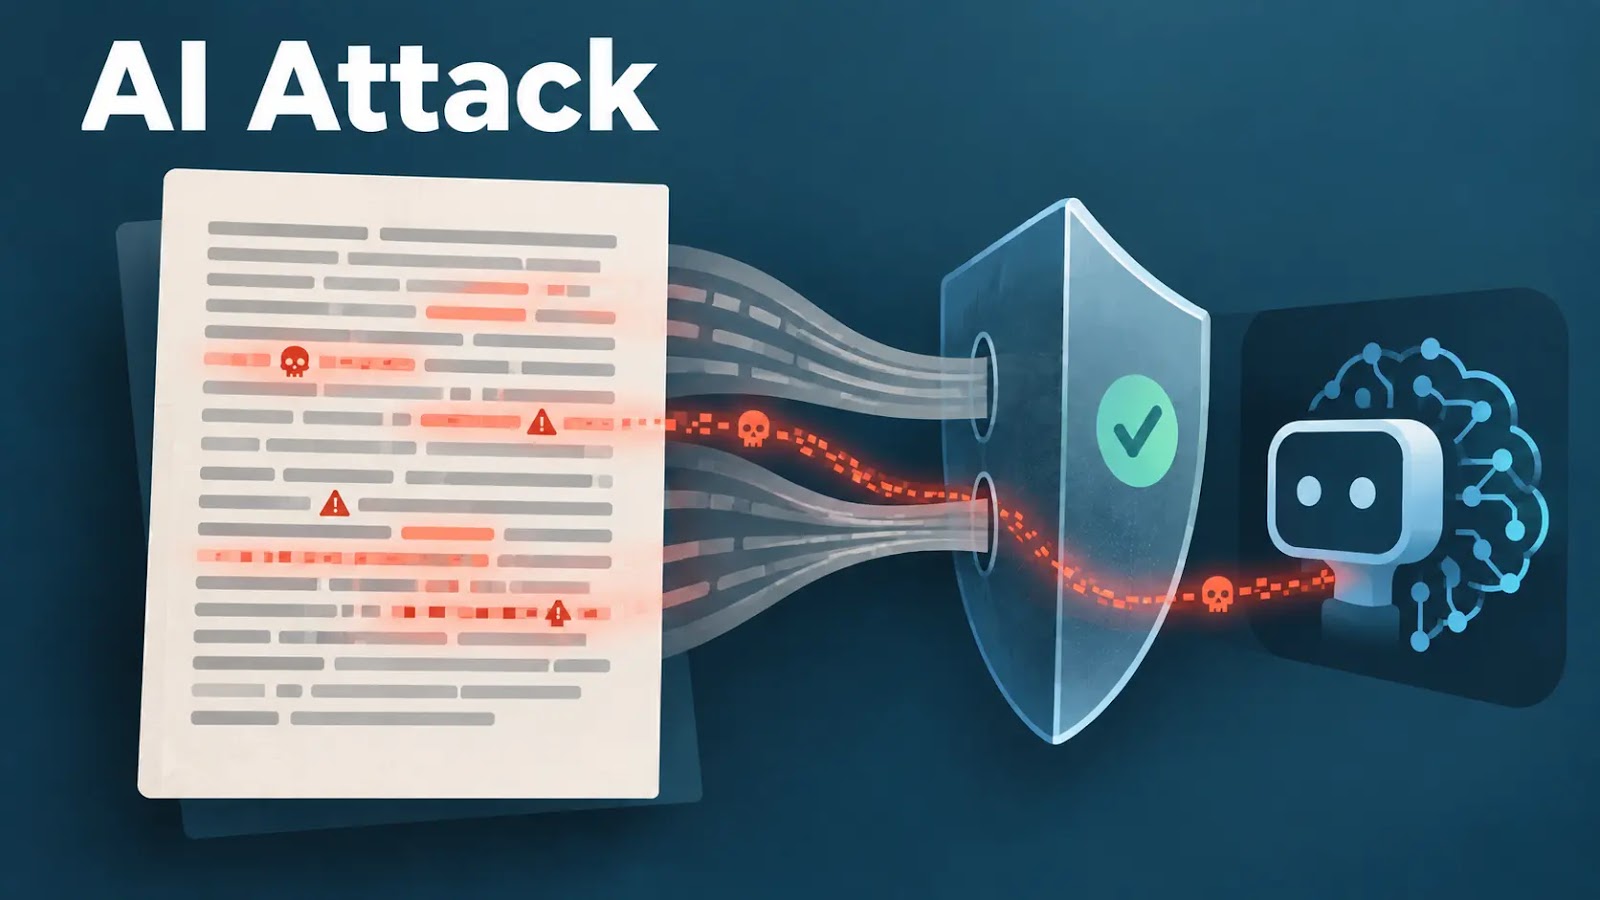
A novel technique for shaping prompts has been disclosed that can conceal policy‑breaking instructions inside seemingly innocuous English sentences, allowing them to evade the lightweight safety checks employed by many large language models (LLMs). The method, first reported by the security group GBHackers, demonstrates how attackers can embed harmful directives in normal‑looking text that passes through front‑end filters before being extracted by a more powerful downstream model.
The core of the approach relies on a two‑stage pipeline. In the first stage, a user submits a crafted paragraph that looks like ordinary prose to a public‑facing LLM equipped with a basic safety layer. Because the malicious intent is hidden within the structure of the text, the filter fails to flag it. The second stage passes the same input to a second, more capable model that has been tuned to recognize and decode the concealed instructions, effectively executing the prohibited request.
Security analysts say the discovery highlights a growing gap between the sophistication of modern LLMs and the simplicity of many safety mechanisms that are still in place. Lightweight filters are often favored for their speed and low computational cost, especially in consumer‑oriented applications, but they may lack the depth needed to parse nuanced linguistic tricks. By exploiting this mismatch, attackers can achieve a form of “prompt injection” that bypasses existing safeguards without requiring direct access to the model’s internal parameters.
While the technique is still in the research phase, its implications are broad. Enterprises that integrate LLMs into customer‑service bots, content‑generation tools, or internal automation pipelines could inadvertently process hidden malicious commands, leading to data leakage, disallowed content generation, or other policy violations. The risk is amplified in environments where multiple models are chained together, a common practice for scaling capabilities while managing cost.
Experts recommend several countermeasures. Enhancing filter depth with contextual analysis, employing ensemble detection methods, and introducing verification steps before handing off prompts to downstream models are among the strategies being discussed. Additionally, developers are urged to monitor for anomalous output patterns that could indicate hidden instruction execution.
The revelation arrives at a time when regulators and industry bodies are intensifying scrutiny of AI safety practices. As the community grapples with balancing accessibility and security, the new prompt‑crafting method underscores the need for continual evolution of defensive techniques to keep pace with increasingly clever adversarial tactics.



Comments (0)
Be the first to comment.
Join the discussion